
Evaluating the informational efficiency of prediction markets requires rigorous statistical scoring rules that measure epistemic accuracy and probabilistic calibration. By decomposing the Brier Score into its fundamental components—Reliability, Resolution, and Uncertainty—quantitative researchers can benchmark market clearing prices against polling aggregates, identify the Favorite-Longshot Bias, and isolate persistent forecast edges.
1. The Efficient Market Hypothesis in Information Aggregation Venues
Rooted in Friedrich Hayek's seminal insight on the price mechanism as a decentralized information aggregator, prediction markets operate as dynamic Bayesian belief networks. In traditional equity or commodity markets, prices reflect cash flow expectations discounted by subjective risk premia. In cash-settled binary prediction markets, however, contracts have bounded payoffs ($0.00 or $1.00), forcing prices to behave directly as consensus probability measures.
Under the Strong-Form Efficient Market Hypothesis (EMH), a prediction market clearing price P_t incorporates all public and private information:
E[o_{t+k} | F_t] = P_t
Where o_{t+k} ∈ {0, 1} is the verified binary outcome at resolution time t+k, and F_t represents the filtration of all information available at time t. If the market is perfectly efficient, the sequence of price revisions must form a martingale with zero serial autocorrelation:
E[P_{t+1} - P_t | F_t] = 0
To test whether this mathematical condition holds empirically, researchers rely on proper scoring rules that penalize both overconfidence and miscalibration.
2. The Brier Score: Quadratic Scoring Metric for Binary Probabilities
Introduced by meteorologist Glenn W. Brier in 1950, the Brier Score is a strictly proper scoring rule designed to evaluate probabilistic forecasts against binary realized outcomes.
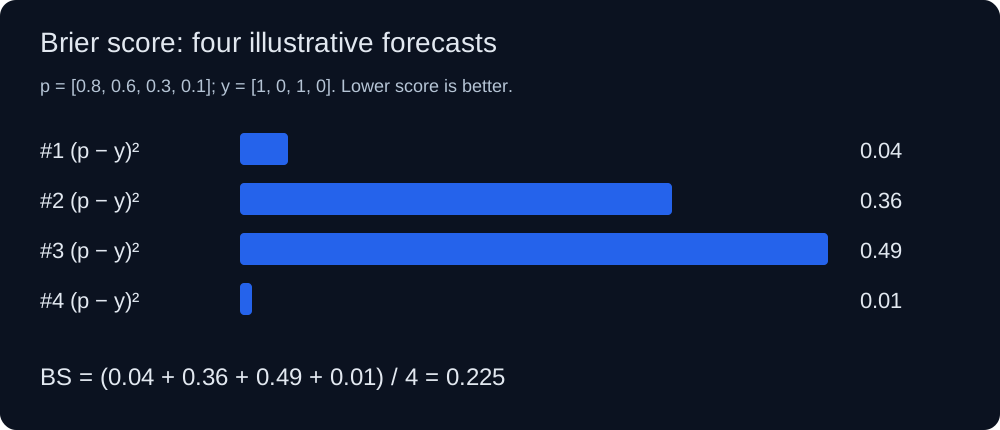
Let N denote the total sample size of resolved events. For each event t ∈ {1, 2, ..., N}, let f_t ∈ [0.00, 1.00] represent the forecast probability (the market clearing price P_m), and let o_t ∈ {0, 1} represent the actual binary outcome (1 for event occurrence, 0 for non-occurrence). The Brier Score (BS) is defined as the mean squared error:
BS = (1 / N) * ∑_{t=1}^N (f_t - o_t)^2
Key mathematical properties of the Brier Score:
- Bounded Interval: BS ∈ [0.00, 1.00]. A lower score indicates superior predictive accuracy.
- Perfect Deterministic Forecaster: If a forecaster predicts f_t = 1.00 for all occurring events and f_t = 0.00 for all non-occurring events, BS = 0.000.
- Uninformative Benchmark: A naive forecaster assigning f_t = 0.50 to every binary event produces a baseline BS = (0.50 - 1)^2 = 0.250. Any forecasting system with BS > 0.250 performs worse than an uninformative coin toss.
- Strict Propriety: The expected Brier Score is strictly minimized if and only if the reported probability f_t equals the forecaster's true internal subjective probability p_t. It is mathematically impossible to game a proper scoring rule through strategic under- or over-reporting.
3. The Murphy Decomposition: Reliability, Resolution, and Uncertainty
In 1973, Allan H. Murphy proved that the aggregate Brier Score can be partitioned analytically into three orthogonal, economically interpretable components.
Suppose forecasts are partitioned into K discrete probability bins k ∈ {1, 2, ..., K} with unique forecast values f_k (e.g., 10% bins: 0.05, 0.15, ..., 0.95). Let n_k denote the number of forecasts in bin k, and let o_k denote the observed empirical success frequency in bin k:
o_k = (1 / n_k) * ∑_{t ∈ bin_k} o_t
Let ¯o denote the overall base rate of event occurrence across the entire sample: ¯o = (1 / N) * ∑ o_t. Murphy's algebraic identity states:
BS = Reliability - Resolution + Uncertainty
Where each component is defined explicitly as:
Reliability = (1 / N) * ∑_{k=1}^K n_k * (f_k - o_k)^2
Resolution  = (1 / N) * ∑_{k=1}^K n_k * (o_k - ¯o)^2
Uncertainty = ¯o * (1 - ¯o)
The deep structural insights provided by the Murphy decomposition:
- Reliability (Calibration Error): Measures how closely the forecast probabilities match the observed empirical frequencies. In a perfectly calibrated market, o_k = f_k for all bins, yielding Reliability = 0.000. Any positive value represents miscalibration penalty.
- Resolution (Discriminative Power): Measures the forecaster's ability to separate outcomes into distinct high- and low-probability clusters relative to the climatological base rate ¯o. Higher Resolution subtracts directly from the Brier Score, improving overall accuracy.
- Uncertainty (Inherent Entropy): Quantifies the intrinsic unpredictability of the event domain. If ¯o = 0.50 (maximum entropy), Uncertainty reaches its peak at 0.250. Uncertainty depends solely on event realization and is independent of forecaster skill.
4. Calibration Table: 3,236 Resolved Polymarket Markets
The table applies the decomposition to real data: 3,236 resolved Yes/No markets on Polymarket with volume of at least $50,000 that closed between 13 March 2023 and 5 October 2026, using the last traded Yes price 24 hours before close. Bands are fixed 0.1 intervals. The dataset, the analysis script and the full results are in our calibration study; an earlier version of this table used 2,500 synthetic contracts and has been replaced.
| Price Band | Markets (n_k) | Mean Price (f_k) | Resolved Yes (o_k) | f_k - o_k | Reliability Contribution | Reading |
|---|---|---|---|---|---|---|
| 0.00 - 0.10 | 2,433 | 0.0086 | 0.0037 | +0.0049 | 0.00002 | Overpriced (clear) |
| 0.10 - 0.20 | 106 | 0.1432 | 0.1132 | +0.0300 | 0.00003 | Overpriced, within noise |
| 0.20 - 0.30 | 73 | 0.2548 | 0.2192 | +0.0356 | 0.00003 | Overpriced, within noise |
| 0.30 - 0.40 | 39 | 0.3415 | 0.2308 | +0.1107 | 0.00015 | Overpriced, within noise |
| 0.40 - 0.50 | 36 | 0.4450 | 0.4444 | +0.0006 | 0.00000 | Close to calibrated |
| 0.50 - 0.60 | 41 | 0.5522 | 0.7317 | −0.1795 | 0.00041 | Underpriced (clear) |
| 0.60 - 0.70 | 36 | 0.6542 | 0.8611 | −0.2069 | 0.00048 | Underpriced (clear) |
| 0.70 - 0.80 | 59 | 0.7511 | 0.8644 | −0.1133 | 0.00023 | Underpriced (clear) |
| 0.80 - 0.90 | 66 | 0.8506 | 0.8636 | −0.0130 | 0.00000 | Close to calibrated |
| 0.90 - 1.00 | 347 | 0.9801 | 0.9856 | −0.0055 | 0.00000 | Close to calibrated |
"Clear" means that the 95% interval for the return from buying Yes in that band excludes zero (for the lowest band, this return is computed on the 669 contracts priced above 0.5¢). The reliability contributions add up to 0.0013. With resolution 0.1210 and uncertainty 0.1457, Murphy's identity gives 0.0013 - 0.1210 + 0.1457 ≈ 0.0260, against a measured Brier score of 0.0259; the small gap comes from rounding and from the spread of prices within each band.
5. The Favorite-Longshot Bias: What the Data Show
The Favorite-Longshot Bias (FLB) is a pattern documented in horse-race betting and other wagering markets: longshots are overpriced relative to how often they win, and favourites are underpriced.
Our data show it at the low end. In the lowest band the mean price is 0.86%, yet only 0.37% of those contracts resolved Yes: longshots were overpriced by a factor of more than two, although the gap is only half a cent in absolute terms. Buying Yes on the contracts in that band priced above 0.5¢ returned −67% on average (95% interval −92% to −43%). At the top, contracts from 90¢ averaged 98.01% and resolved Yes 98.56% of the time, so favourites were slightly underpriced, but buying them returned only +0.60% (−0.71% to +1.91%). The largest absolute errors were in the middle: in the 50–80¢ bands Yes resolved 73–86% of the time against mean prices of 55–75%, on only 136 markets.
Two caveats limit how far this generalizes. About three quarters of the low-priced contracts (1,792 of 2,433) come from multi-outcome events whose outcomes are correlated; outside those events the lowest band shows 0.84% priced against 0.78% resolved. And the sample covers Polymarket only, with volume of at least $50,000.
The literature offers three explanations for the bias:
- Recreational Preference for Convexity (Lottery Utility): Retail traders exhibit risk-seeking preferences over small stakes, systematically overpaying for low-cost lottery tickets with 20x payouts while avoiding high-probability 1.05x payouts.
- Capital Inefficiency: As our Kelly criterion analysis shows, shorting a 5% longshot locks up $0.95 of capital for a 5.26% return. Large traders are reluctant to tie up capital for such thin margins, which can leave longshots overpriced.
- Prospect Theory Probability Weighting: Daniel Kahneman and Amos Tversky demonstrated that human decision-makers overweight low probabilities (π(p) > p for p < 0.10) and underweight moderate-to-high probabilities.
6. Log-Loss and Kullback-Leibler Information Divergence
While the Brier Score measures quadratic error, information theorists use the Logarithmic Scoring Rule (Log-Loss / Cross-Entropy), which punishes confident mistakes much harder:
LogLoss = - (1 / N) * ∑_{t=1}^N [ o_t * ln(f_t) + (1 - o_t) * ln(1 - f_t) ]
As the probability assigned to an outcome that does not happen approaches 1, the penalty grows without bound; at 99.9% it is already -ln(1 - 0.999) = -ln(0.001) = 6.908. The expected log-loss equals the entropy of the true distribution plus the Kullback-Leibler (KL) divergence D_{KL}(P_{true} || P_{market}), so on a fixed set of events a lower log-loss means a smaller divergence from the truth:
D_{KL}(P || Q) = ∑_{x} P(x) * ln( P(x) / Q(x) )
The same quantity measures trading opportunity. A trader who knows the true probabilities P and bets Kelly against market prices Q, with no fees, grows capital at an expected log rate equal to D_{KL}(P || Q); the closer the market is to the truth, the less there is to earn. For reference, our 3,236 Polymarket markets have a log-loss of 0.0914 at 24 hours before close and 0.1449 at 7 days (3,104 markets with a 7-day price).
7. Prediction Markets vs. Polls and Expert Forecasts
The best-known long-run comparison is Berg, Nelson and Rietz (2008, International Journal of Forecasting). They compared Iowa Electronic Markets vote-share prices with 964 national polls over the five US presidential elections from 1988 to 2004. The market was closer to the final result 74% of the time, and its advantage was clearest more than 100 days before the election. That is a head-to-head comparison on the same questions, not a Brier score.
Our data cannot rank markets against polls, because we have no matching poll forecasts. They do show how much a Brier score depends on the question set. The 24-hour Brier score of 0.0259 looks excellent mostly because 2,780 of the 3,236 markets (86%) were already priced below 10¢ or at 90¢ and above a day before close. Seven days before close the score is 0.0435 on the 3,104 markets with a 7-day price, and 79% of them were at those extremes. Brier scores are only comparable on the same events at the same horizon, so a single headline number for "prediction markets" versus "polls" means little without that match.
8. Interactive Calibration Analyzer & Brier Score Decomposition
To verify your own predictive models against historical market baselines, quantitative analysts utilize automated calibration pipelines that partition predictions into decile bins and generate Murphy decomposition matrices.
You can audit your forecasting accuracy, compute Murphy Reliability and Resolution scores, and visualize reliability diagrams using our zero-runtime client-side tool:
Launch Brier Score Calibration Analyzer →
By mastering the mathematics of scoring rules and calibration decomposition, quantitative researchers quantify forecasting edge, detect structural market anomalies, and deploy capital with scientific precision.
